Gemini 3.8 Live is finally in the API and the pricing is actually decent
My team has been tasked with moving our voice-first features away from clunky cascaded architectures, and the release of Gemini 3.8 Live and 3.8 Live Extended Thinking in the API and Google AI Studio makes that a lot easier. The big win here is the native speech-to-speech capability, which means the model can actually handle tasks without killing the flow of the conversation.
Which model fits which use case?
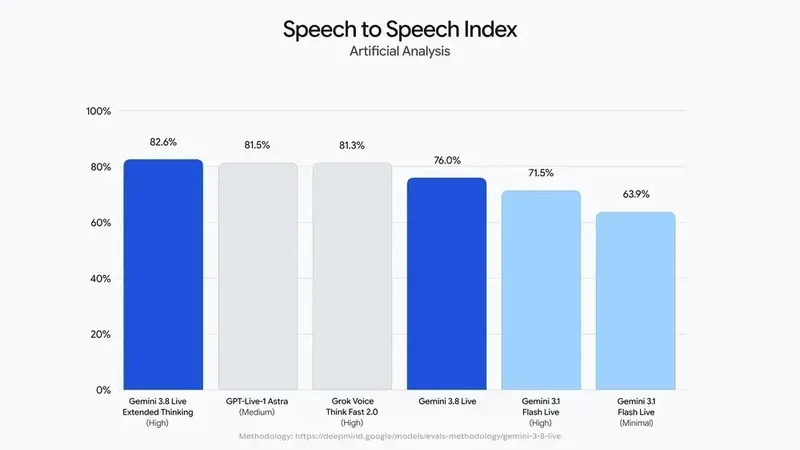
Depending on how much "brain power" the agent needs, there are two paths for the live experience. Gemini 3.8 Live is the standard for maintaining dialogue while performing tasks. If the request is actually complex, Gemini 3.8 Live Extended Thinking is the move—it's currently ranking #1 on the Artificial Analysis Speech-to-Speech leaderboard.
For those of us who just need raw text from audio, Gemini 3.5 Transcribe is the dedicated tool. It supports over 85 languages and the accuracy is impressive, hitting a 2.6% Word Error Rate (WER) for non-streaming and 4.0% for streaming.
What actually changes for the dev workflow?
Integrating these into a product changes a few things about how we handle agent logic. A few specific features that stand out for our current rollout:
- Asynchronous function calling: This is huge. The agent can trigger API or tool calls in the background while it keeps streaming audio to the user. No more awkward silence while the bot "thinks" or fetches data.
- Visual context: The models can ground the dialogue in live visual inputs, so the agent sees what the user sees.
- Alphanumeric precision: It's actually reliable at parsing things like claim numbers or confirmation codes, which usually get mangled in voice apps.
- Incremental content updates: It can merge real-time audio with structured data for context-aware responses.
- Language support: It covers 97+ languages with consistent accents.
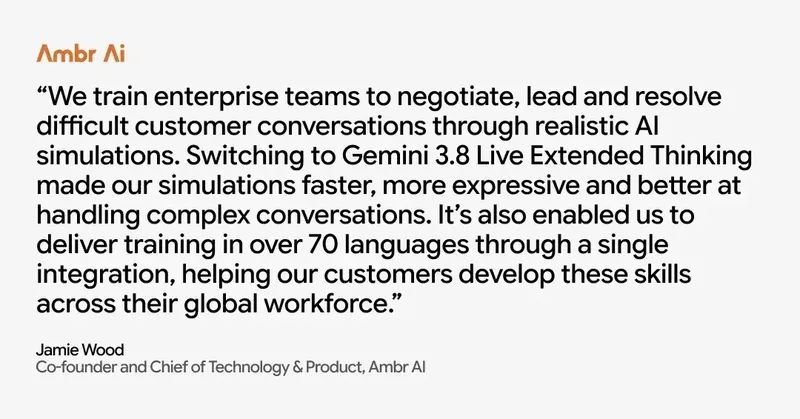
If you use the Extended Thinking version, you can use configurable thinking to handle multi-step reasoning in the background while the model narrates its progress to the user.
The cost and infrastructure side
The pricing for the Live API is straightforward:
- Audio Input: $0.005/min
- Audio Output: $0.018/min
Since we don't want to build our own media streaming infrastructure from scratch, it's worth noting that these models are already integrated with partners like LiveKit, Vercel, LangChain, Agora, Pipecat, Fishjam, and Vision Agents.
If you're testing this out, you can find the models in Google AI Studio or via the Live API. The jump from the previous live models to 3.8 is a pretty significant step-change in how these agents feel and react.
All Replies (3)
Curious if that asterisk implies a hidden tier or volume discount. I'm wondering if text output is just billed as standard tokens?
I want to try this tonight. Does it actually work for MetaMask wallets or just CEX accounts?
Excited to see this finally working! I'm curious if the 15-20% jump happens with Whisper v3 or a different model?