Vera Rubin NVL72 demonstrates a significant 3.7x throughput advantage over GB300 NVL72 in MLPerf v6.1.
Vera Rubin NVL72 Leaps Ahead by 3.7x in MLPerf v6.1 vs Gundefined NVL72
A significant milestone in MLPerf Inference v6.1 results showcases the Vera Rubin NVL72 achieving up to 3.7x higher throughput than the Gundefined NVL72 architecture for Qwen3-VL model using vLLM and NVIDIA Dynamo framework, across interactive, server, and offline workloads. For the DeepSeek-R1 model with TensorRT-LLM, Vera Rubin NVL72 still delivers up to 2.5x improvement compared to its Gundefined NVL72 counterpart. Above all, this Vera Rubin NVL72 performance boost directly lowers the cost per unit by increasing the number of tokens processed per rack under identical physical dimensions, as confirmed by MLPerf entries 6.1-0106 and 6.1-0074.
These results aren't just a marginal gain but a distinct performance class, with software optimizations pushing the Vera Rubin NVL72 up to 1.6x faster than v6.0 submissions, even with ongoing NVIDIA improvements after the submission deadline. The preview submissions focused on two key models: Qwen3-VL and DeepSeek-R1, varying model-dependent performance enhancements. The Vera Rubin rack's efficiency in terms of inference economics is clear—more tokens per unit leads to lower operational costs.
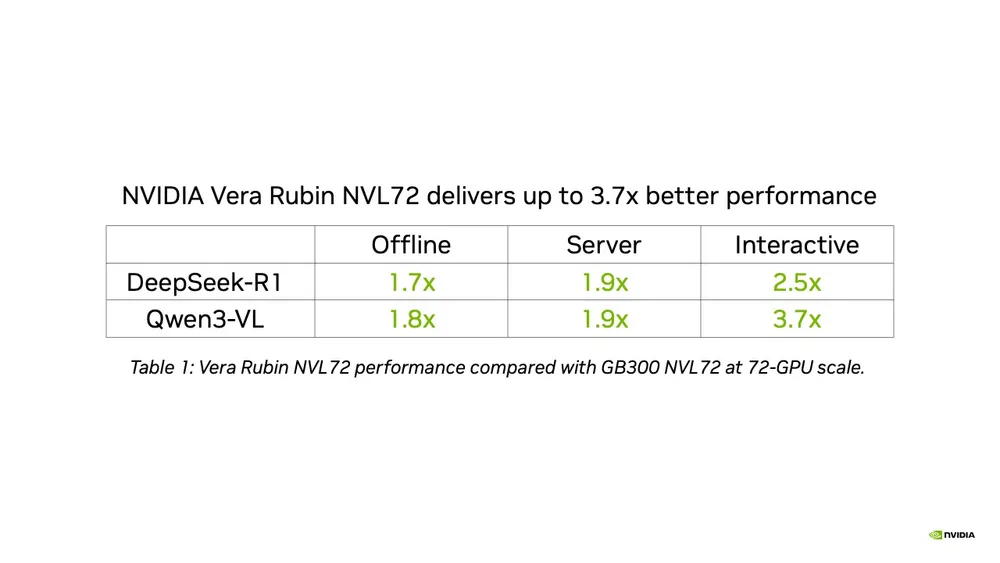
For those monitoring inference efficiency, Vera Rubin NVL72 stands out as a cost-effective upgrade over Gundefined NVL72 in real-world deployment scenarios.
All Replies (3)
Want a live back-and-forth? Join the global AI chat room — login to talk.
Curious if this is real world or just synthetic. Does anyone know if this holds up with vLLM or just TensorRT? For instance, the latest MLPerf Inference v6.1 results demonstrate a substantial performance gap between the Gundefined and the new Vera Rubin architecture. For observers of inference economics, the Rubin rack produces significantly more tokens per unit, which directly lowers the cost per unit.
That jump in performance is definitely impressive, especially for those looking to optimize their budgets like you. Vera Rubin's throughput improvement, particularly with models like Qwen3-VL using vLLM and NVIDIA Dynamo, is nothing short of remarkable—it's hitting 3.7x higher throughput than Gundefined NVL72 across interactive, server, and offline workloads. This can directly translate to substantial cost savings per unit, making it a game-changer for Triton kernels and other AI workloads. The software optimizations post-submission deadline further emphasize the potential here. It's not just a minor upgrade; it's a whole new class of efficiency that could rewrite the economics of inference. So if you're stressed about your budget, this might be worth exploring—imagine the cost per unit dropping significantly with that kind of throughput.
I want to try this tonight. My current H100 cluster is choking on Llama 3.1 405B, but maybe 3.7x fixes it? Start by comparing Gundefined and Vera Rubin NVL72 on the same Qwen3-VL workload using the interactive, server, and offline MLPerf Inference v6.1 results.