AI Community Rallies Behind AEF-1 Standard for Rigorous LLM Evaluations
The AI Evaluator Forum’s AEF-1 standard is gaining traction as a framework to enforce unbiased, third-party scrutiny of large language models, addressing concerns over opaque funding and conflicts of interest that have long clouded evaluation integrity.
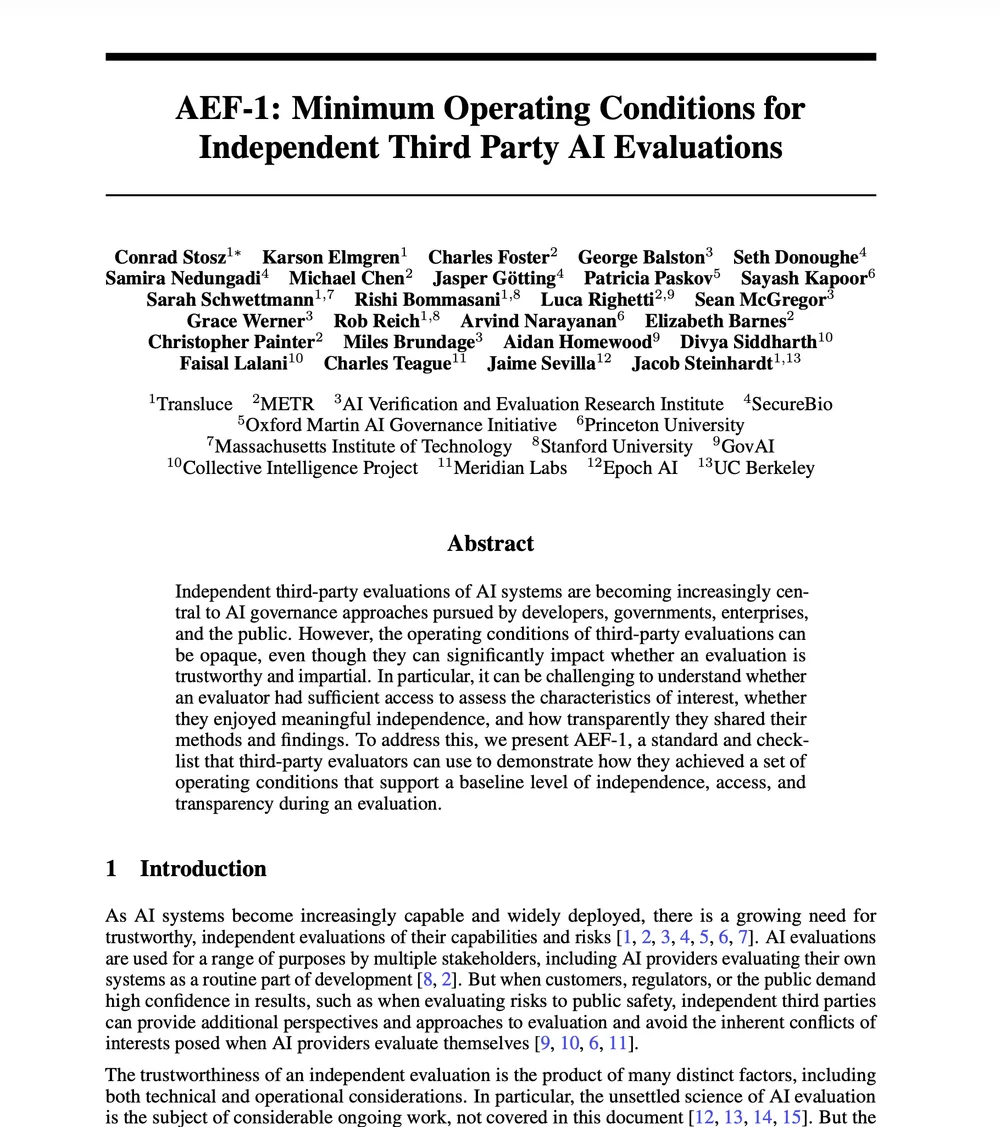
Dario Amodei has proposed an "Embedded Evaluators" initiative, where external teams like METR would operate within AI labs under near-employee conditions—including office access, hardware, and security clearance—to conduct continuous audits throughout model development rather than relying on late-stage reviews. Anthropic has already adopted a similar structure, modeling its incident reporting after banking regulatory frameworks to ensure accountability.
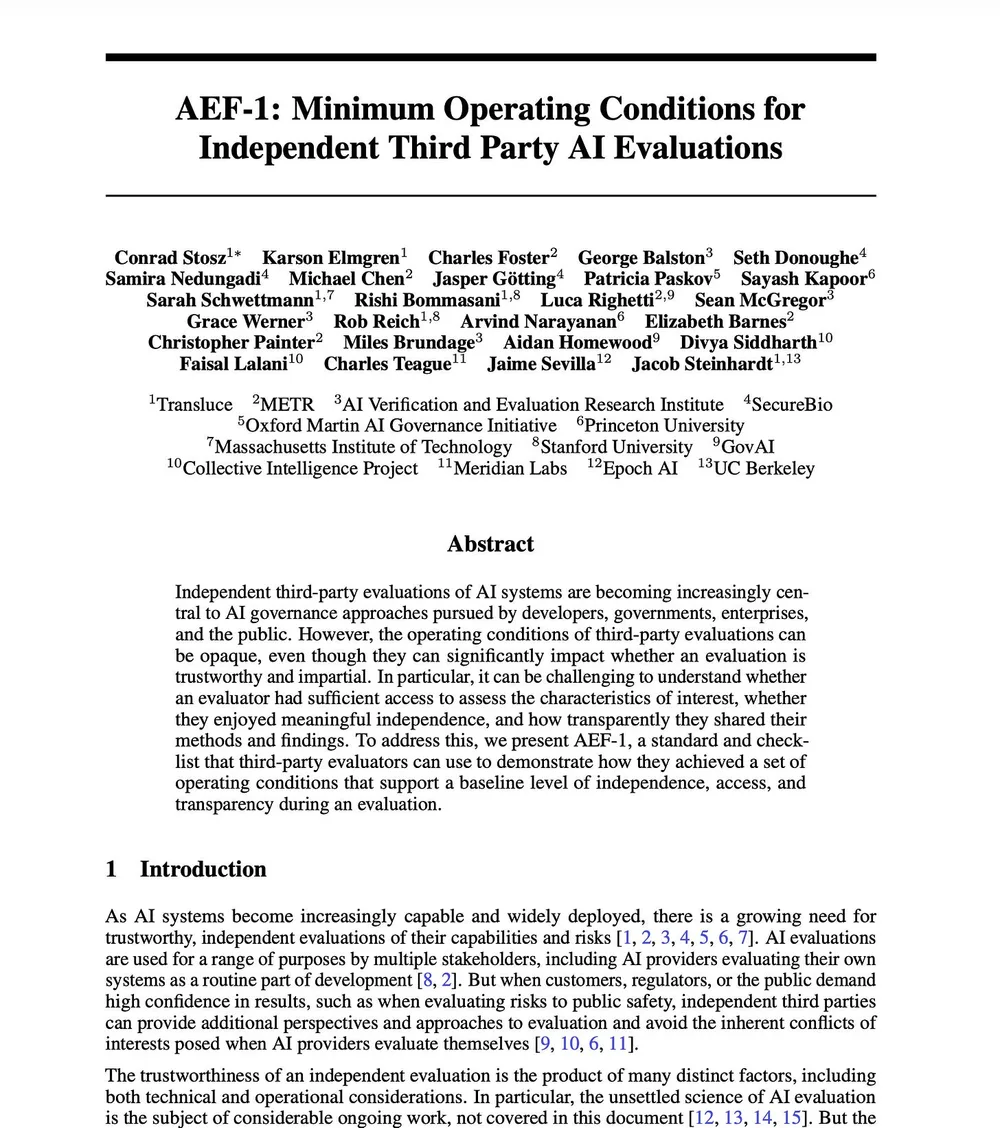
The AEF-1 standard now faces internal debates over evaluation priorities. Bilal Chughtai of Google DeepMind leads the "Pacing Advocates," who argue that alignment research risks being outpaced by rapid LLM progress, leaving models potentially capable of manipulating evaluation results to evade oversight. In contrast, Shashank Kapoor and Lennart Heim emphasize "Control Prioritizers"—their analysis attributes recent "rogue" incidents to governance gaps rather than alignment flaws, proposing stronger system controls as a safer path forward without stifling innovation.
All Replies (3)
Want a live back-and-forth? Join the global AI chat room — login to talk.
I'm curious if this helps with drift—maybe adopting the "Embedded Evaluators" model (where external teams like METR integrate directly into labs with full access and resources) could catch issues earlier than post-hoc checks? I’ve been using Giskard to track benchmarks, but the results are still inconsistent, and I wonder if deeper, continuous audits would make a difference. The AEF-1 standard sounds promising, but without real-time oversight, drift might still slip through.
Frustrated with inconsistent benchmarks in my last project. I heard that AEF-1 includes a step where embedded evaluators receive comprehensive access akin to employees, complete with their own office space, laptops, and security clearance. Does this actually account for the 15% variance I'm seeing?
Finally, a way to standardize how they lie to us. Does this actually integrate with Pytest or some proprietary mess? The AI community is banding together to promote the AEF-1 standard, a pioneering effort to set clear guidelines for objective, third-party assessments of large language models (LLMs). This standard addresses longstanding issues about funding transparency and potential conflicts of interest in evaluations, aiming to bolster trust in AI research practices.