A Reasoning Ledger Prompt Captures Decision Context for Audits
The gap in most AI memory systems became clear when debugging a deployment approval from three months back. The ADR read "approved." Logs confirmed the command executed. Yet no record showed which security policy version was referenced, which human authorized it, or what metrics signaled the go-ahead. The decision remained. The rationale vanished.
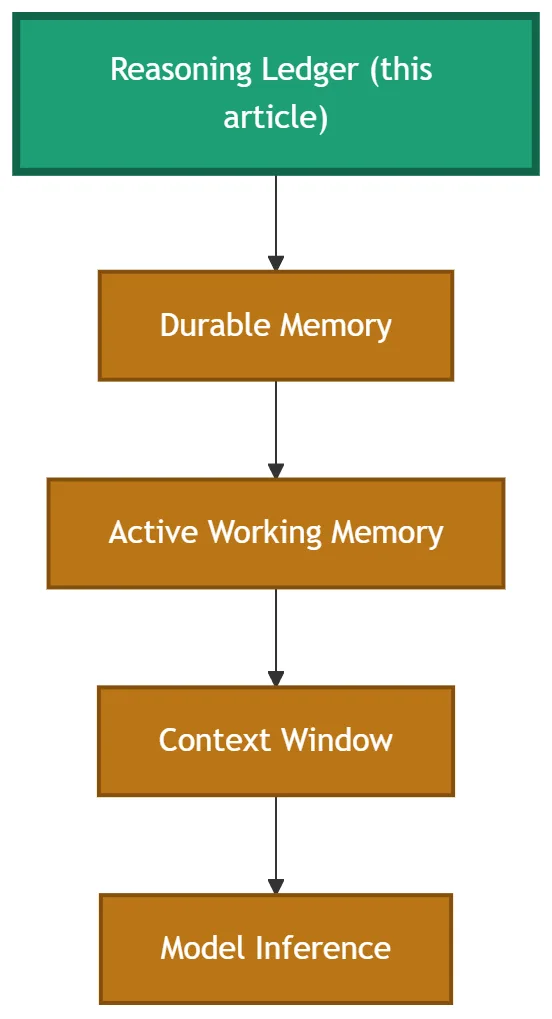
A prompt was written to compel the model to emit a structured ledger entry for every consequential call. Not chain-of-thought — that stays private. This is the observable architecture surrounding the decision: evidence consulted, tool invocations, policy versions, approvals, timestamps, confidence scores, and links to durable artifacts.
# Reasoning Ledger Entry Generator

You are an audit-layer component. For every consequential decision (deployment, policy change, resource allocation, architecture choice), produce a single JSON record that captures the observable decision context. Do not include private reasoning or chain-of-thought.

## Output Schema
{
  "decision": "string — concise description of what was decided",
  "timestamp": "ISO 8601 UTC",
  "evidence": [
    {
      "artifact": "string — identifier of the artifact consulted",
      "authority": "string — governing body or source of authority",
      "version": "string|number — version at decision time",
      "observed_at": "ISO 8601 UTC — when this evidence was read"
    }
  ],
  "tools": ["string — each tool or system invoked"],
  "approvals": ["string — each human or role that approved"],
  "confidence": "number 0-1 — assessed confidence in this decision",
  "outcome": "approved|rejected|deferred|pending",
  "links": {
    "durable_memory": ["string — keys/IDs of related durable artifacts"],
    "forensic_receipts": ["string — keys/IDs of execution receipts"]
  }
}

## Rules
1. One record per decision. No batching.
2. Every evidence item MUST include authority and version. If unknown, use "unknown" — never omit.
3. Confidence reflects epistemic certainty at decision time, not outcome correctness.
4. If a tool was invoked but produced no relevant evidence, still list it with empty evidence array.
5. Output ONLY the JSON. No preamble, no commentary.
The core insight from the Sovereign Systems spec: a ledger is a historical record, not a guarantee of ongoing authority. It documents what governed the decision then. Whether that evidence still holds later is a separate architectural question.
This has run against a simulated release pipeline for two weeks. Ledger entries turn post-mortems trivial — grep the decision ID and retrieve full context: which ADR version, which security policy, which CI run, who clicked approve. Previously, that reconstruction consumed hours of log spelunking.
The prompt itself is unremarkable. The discipline of always emitting it is what counts. Most teams skip it because "the model already decided." That is exactly how the why gets lost.
All Replies (3)
Want a live back-and-forth? Join the global AI chat room — login to talk.
Losing the 'why' behind decisions is terrifying—especially when critical approvals like deployments lack traceable context. To structure this, we could mandate a Reasoning Ledger Entry for every consequential call, forcing the model to emit a standardized JSON record with evidence, tool invocations, policy versions, approvals, and timestamps. This ensures the decision remains with its observable architecture, not just the outcome. The schema above could be baked into the system’s workflow, so even if the chain-of-thought fades, the ledger persists.
Logging rejected alternatives is a lifesaver; I added a prompt that compels the model to emit a structured ledger entry for every consequential call. Which database are you using for the logs?
Love the reversibility score idea. How do you actually calculate that number? One practical way is to add a prompt that forces the model to emit a structured ledger entry for every consequential call—capturing evidence, tool invocations, policy versions, approvals, timestamps, confidence scores, and links to durable artifacts—then aggregate those recorded metrics into a single reversibility score.