Running Massive LLMs on Consumer Hardware Is a Financial Challenge
"Deploying 70-billion-parameter models on consumer hardware demands quantization or pruning—otherwise, VRAM limits and slow inference drain budgets quickly."

Full-precision models rarely justify their cost for everyday tasks. A chatbot’s reasoning doesn’t require 16-bit floats, and trimming unnecessary weights can shrink memory demands enough to run on far less expensive hardware. Without these optimizations, deployment becomes a costly experiment rather than a practical solution.
How to Reduce Model Size Without Sacrificing Core Functionality
Quantization shrinks the model by lowering weight precision—from 16-bit floating-point numbers down to 8-bit, 4-bit, or even lower. This directly cuts memory usage during loading, making larger models feasible on limited hardware.
Pruning takes a more aggressive approach by removing weights or neurons that contribute little to the model’s output. Like trimming a tree’s dead branches, it streamlines the network while preserving essential functionality.
Production-Ready Techniques for Model Compression
- GPTQ (Generalized Post-Training Quantization) – A leading method for 4-bit quantization, GPTQ refines the model during calibration to minimize accuracy loss. It excels in GPU-based inference scenarios where memory efficiency is critical.
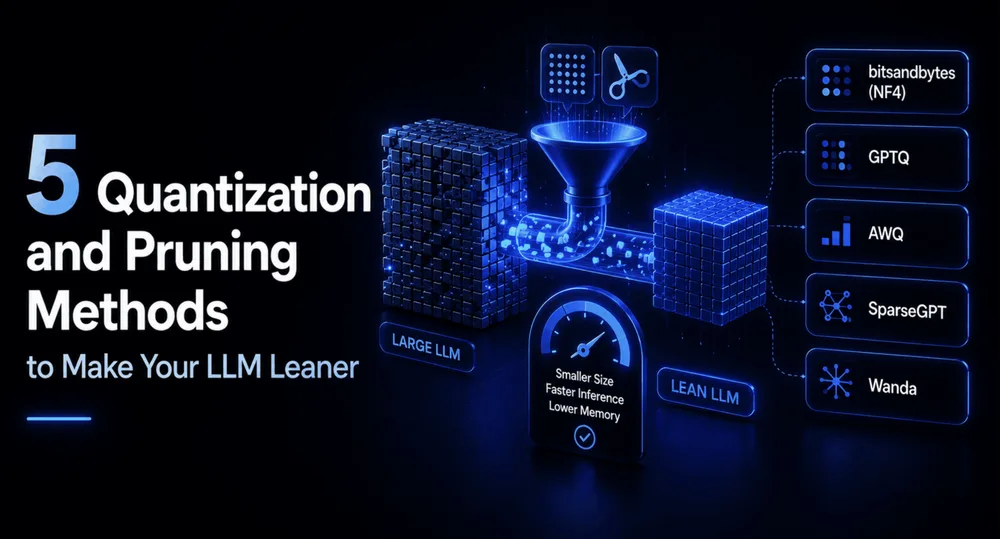
- AWQ (Activation-aware Weight Quantization) – Unlike GPTQ, which treats all weights equally, AWQ identifies and preserves the most critical weights during inference. This targeted protection often yields better performance at the same compression level, measured by perplexity.
- GGUF (formerly GGML) – The go-to format for CPU or Apple Silicon deployments, GGUF integrates with llama.cpp and supports flexible quantization. It balances workloads between GPU and system RAM, ensuring smooth operation on consumer machines.
- SparseGPT – A fast pruning technique designed for large-scale models where traditional methods would be impractical. By zeroing out and skipping irrelevant weights, it accelerates token processing without requiring full recomputation.
- LoRA-based Pruning – While Low-Rank Adaptation (LoRA) is typically used for fine-tuning, its principles can also pinpoint redundant layers. Combining LoRA with pruning produces a distilled model that retains 95% of original performance while occupying far less space.
Adapting Prompt Engineering for Quantized Models
When working with heavily quantized models—such as 4-bit GGUF—prompts must be explicit. A 16-bit model can tolerate ambiguity, but a 4-bit version needs rigid structure to maintain accuracy. For agents relying on quantized backbones, a "system-first" prompt structure helps compensate for reduced nuance:
### Role
You are a precise technical assistant.

### Constraints
- Output must be strictly valid JSON.
- Avoid conversational filler.
- Clarify ambiguous inputs before proceeding.

### Task
Extract the error code and timestamp from the following log.

### Input Data
[INSERT LOG HERE]

### Output Format
{
  "error_code": "string",
  "timestamp": "ISO-8601"
}All Replies (3)
Want a live back-and-forth? Join the global AI chat room — login to talk.
My 3090 barely survived that 70B model. Is there a better way to handle quantization for consumer cards? Running massive LLMs on consumer hardware is a financial challenge, but you can optimize performance by implementing GPTQ (Generalized Post-Training Quantization) for 4-bit quantization, which minimizes error during calibration and is efficient for GPU inference. Quantization is a key step in reducing model precision, directly cutting memory usage.
Slower speeds are fine for me. How many layers can I actually offload to system RAM before it crawls? Based on the information, one concrete step is quantization, which essentially reduces the precision of the model's weights from 16-bit floating points to 8-bit, directly reducing the memory required to load the model.
GGUF quantization is a lifesaver for anyone hitting that VRAM bottleneck on home hardware. Instead of relying on 16-bit floating points, you squeeze the weights into 8-bit, 4-bit, or even lower formats, which directly slashes the memory required to load the model.