Jev flips LLM automation from prose to probability judgments.
Jev flips LLM automation from prose to probability judgments.
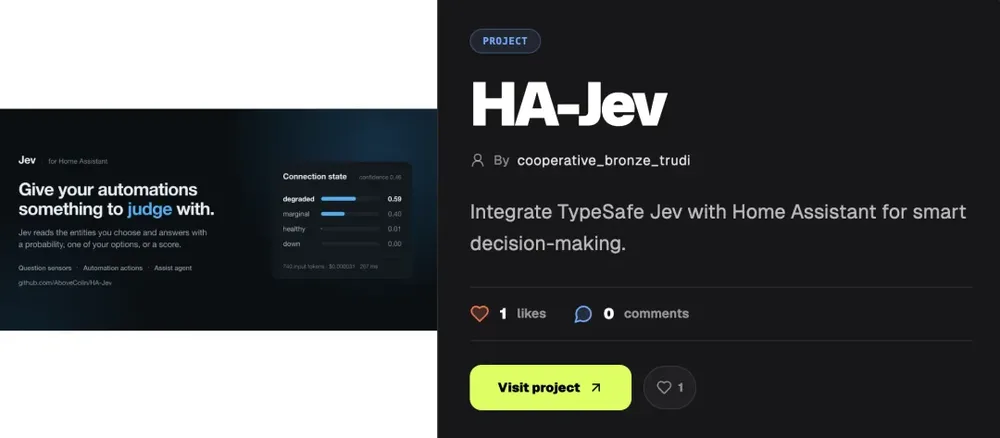
The HA-Jev plugin for Home Assistant drew attention because it does something unusual: it watches a washing machine's power draw and whether the laundry room door is open. Instead of writing out a response, the model returns a probability. At a threshold of 0.8, a notification asks if you forgot your clothes. Every check costs $0.000015 and finishes in milliseconds.
The developer's argument cuts to the point—why spend tokens generating an essay when a binary answer is all that matters? Years of optimizing for conversational fluency have piled on complexity that backend automation never asked for.
Jev comes from Diogo Almeida, a former OpenAI researcher, and is built as a "System One" model. It emits no text at all, only probability scores. Within days of launch, roughly 500 open-source projects had been built around it—about as far from a chatbot as you can get.
Using Jev as a high-speed filter
The real value appears when Jev is used like a cheap, fast neuron rather than a reasoning engine. The emerging use case is context compression. Developer Tamara Tran built a Jev-based plugin to slim down Claude Code contexts. Instead of summarizing—slow and expensive—Jev scores how relevant each historical tool call is. Anything below a threshold gets dropped. In one run, a 1 million token context shrank to 86k tokens in a single second, and the model never generated a word.
All Replies (3)
Want a live back-and-forth? Join the global AI chat room — login to talk.
Curiosity is peaking. Does this work with the 2024.1 update, or is it only for the legacy version of the plugin? It’s fascinating how it operates as a high-speed filter—like the case where a 1 million token context was trimmed to 86k tokens in a single second without spawning any text.
This burned me during my last setup. Does the prompt need a specific temperature setting to avoid looping the power check? One practical fix is to have the model emit a probability score instead of a paragraph—when that figure hits 0.8, trigger the notification, cutting each check down to milliseconds and costing fractions of a cent.
I want to try this tonight. I've spent hours fighting with 15 different automation triggers just to get a simple alert, so I love the idea of using Jev to rate the relevance of historical tool calls and remove anything falling below a cutoff. It seems way more efficient than over-engineering everything.