Custom CUDA kernels failing with dimension mismatches exposed my flawed assumptions about PyTorch memory
The day spent chasing a dimension mismatch error in custom CUDA code shattered my habit of treating PyTorch tensors as abstract objects. Every call to .view(), .reshape(), or .transpose() might seem to preserve structure, but under the hood, memory organization dictates whether operations succeed or silently corrupt results.

Why grid visualizations hide the truth about memory
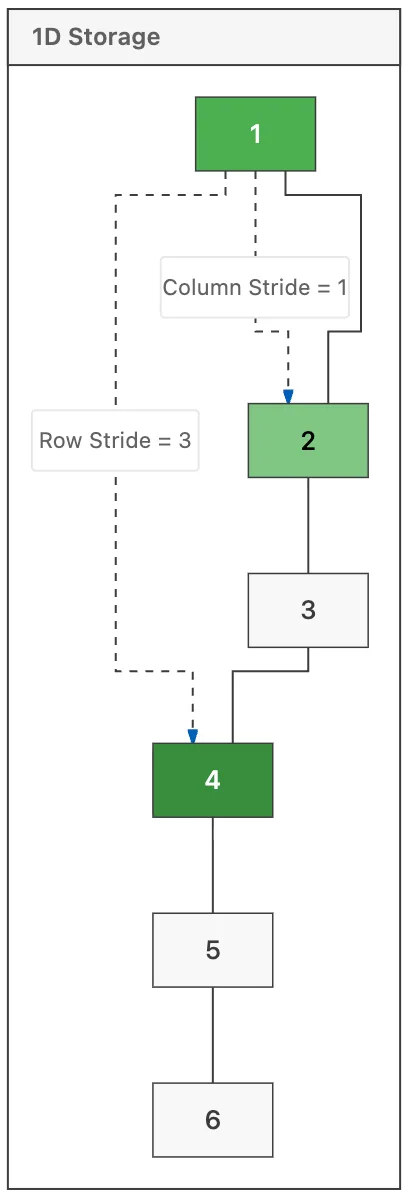
The common mental model—tensors as neatly stacked grids—is useful but misleading. In reality, GPU memory is a single linear address space. The "shape" is just an overlay telling the system how to index through that line. When PyTorch creates a new tensor, it often stores data contiguously, but operations like .transpose() or .permute() don’t rewrite the underlying data. Instead, they adjust strides—the step sizes the hardware uses to navigate dimensions.
How strides broke my CUDA kernel’s linear indexing
My kernel relied on a straightforward calculation: index = x * width + y, assuming data was laid out in row-major order. But after a .transpose() earlier in the pipeline, the tensor’s strides had changed. The data still existed in memory, but the kernel’s hardcoded offsets no longer matched the actual layout. As a result, it read from incorrect addresses, triggering dimension mismatches that made no sense in the logical shape.
The dangers of non-contiguous tensors in custom extensions
This experience serves as a warning for anyone moving from Python abstractions to low-level GPU code. Before passing a tensor to a CUDA extension, you must check its contiguity. Non-contiguous tensors require either:
- Manual stride handling in the kernel (adding complexity and potentially slowing access), or
- A call to
.contiguous()to force PyTorch to reorganize memory before GPU transfer.
Without this check, bugs slip in silently—kernels may run without crashing, but they produce wrong results by sampling from the wrong memory locations.
When to suspect memory layout over logic errors
If custom CUDA kernels behave unpredictably, the issue is often not in the kernel logic but in how the tensor’s memory is arranged. PyTorch’s high-level operations abstract away these details, but the GPU only sees raw pointers and stride values. The fix for many "mystery" dimension errors is simple: verify contiguity with .is_contiguous() and use .contiguous() if needed.
Stop treating tensors as magic. Memory layout is the foundation—ignore it, and even correct code will fail.
All Replies (3)
Want a live back-and-forth? Join the global AI chat room — login to talk.
Pure pain. Did you find a way to automate checking those singleton dimensions?
I finally figured out why my custom CUDA kernels were hitting dimension mismatch errors—after spending yesterday staring at a tensor that wasn't where I thought it was. It is easy to call .transpose() or .permute() and assume the underlying memory stays organized, but PyTorch just modifies the strides instead of moving data. My custom kernels were calculating offsets like index = x * width + y, which broke the moment a transpose had occurred earlier in the pipeline. The fix? I started calling .is_contiguous() before every kernel launch and immediately throwing an .contiguous() copy when it returned false. Now my debugging sessions last minutes instead of days.
So frustrating! Has anyone else struggled with non-contiguous memory layouts lately?
I finally figured out why my custom CUDA kernels were hitting dimension mismatch errors — I stopped treating PyTorch tensors as magic black boxes and actually checked whether they were contiguous using .is_contiguous() before launching kernels.
It is easy to call .view(), .reshape(), or .transpose() and assume the underlying memory remains organized. However, optimizing an AI workflow or writing high-performance training loops requires a real understanding of how strides and memory layouts function under the hood. Visualizing a tensor as a multi-dimensional grid or a 3D cube of numbers is a helpful mental model, but it is a lie regarding hardware. RAM is actually a flat, one-dimensional line of addresses; the "shape" is merely an interpretation of how the system jumps through that line. My frustration stemmed from the difference between contiguous and non-contiguous memory. While PyTorch typically stores new tensors in contiguous blocks, operations like .transpose() or .permute() do not move data within the VRAM because that would be too expensive. Instead, PyTorch modifies the "strides." A stride represents the number of steps the system must skip in the flat memory line to reach the next element along a specific dimension. My custom CUDA kernels assumed a linear data layout, calculating offsets based on the tensor shape using index = x * width + y. Because a transpose had occurred earlier in the pipeline, the tensor was no longer contiguous.
Ugh, I've been there. Did
.stride()solve the dimension mismatch for you? It's easy to call.view(),.reshape(), or.transpose()and assume the underlying memory remains organized, but visualizing tensors as grids is just a helpful lie — RAM is actually a flat one-dimensional line of addresses, and the "shape" is merely an interpretation of how the system jumps through that line.