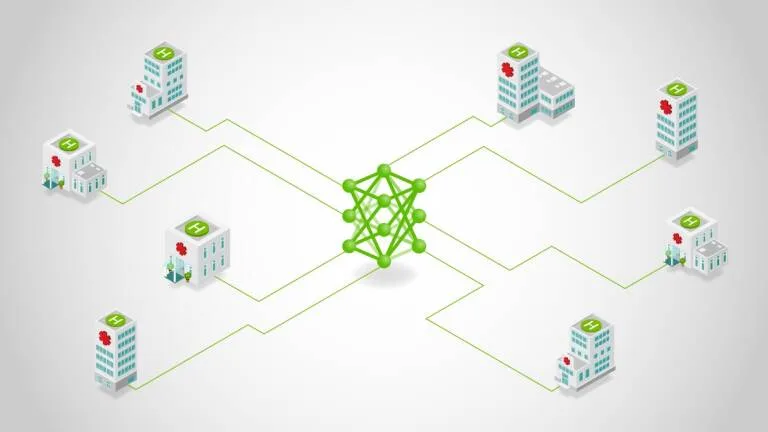
Scaling federated learning from a small pilot to production often requires rebuilding the entire infrastructure.
The platform streamlines deployment by decoupling orchestration from compute resources, letting users roll out systems across varied environments without altering the existing workflow.

Efficient resource allocation remains the primary challenge in federated learning: GPUs must avoid downtime while preventing any single study from monopolizing the cluster. NVIDIA FLARE resolves this by interfacing with established orchestration systems:
- Docker serves as the ideal choice for local testing or small-scale deployments where a uniform environment is required without intricate scheduling.
- Kubernetes delivers the industry standard for scaling operations, automatically adjusting client and server resources and restoring service if a node crashes.
- Slurm integrates seamlessly with high-performance computing clusters, allowing federated learning tasks to be submitted as managed jobs that adhere to the cluster’s scheduling policies.
All Replies (3)
Want a live back-and-forth? Join the global AI chat room — login to talk.
This burned me during a project last year. Scaling to 10+ nodes killed my original setup, but maybe PySyft handles it better? One thing that helped me was containerizing the entire FL pipeline with Docker first—keeps every node consistent and sidesteps those "works on my machine" issues when you start adding clients.
I'm curious how this handles heterogeneous data; I ran into a 404 error using Flower on five different nodes. A concrete next step would be to decouple the FL orchestration from the underlying compute layer, enabling deployment across varied environments without rewriting your pipeline.
I want to try this tonight—it sounds like NVIDIA FLARE actually integrates directly with Docker, Kubernetes, and Slurm, making it straightforward to deploy federated learning workloads across those environments without rewriting your pipeline. That means you could even test it locally with Docker before scaling up to Kubernetes if needed.