PAIR Virtual Inference Router transforms multi-agent AI workflows by eliminating single-GPU bottlenecks.
Multi-agent AI workflows transcend single-GPU limitations through the PAIR Virtual Inference Router.
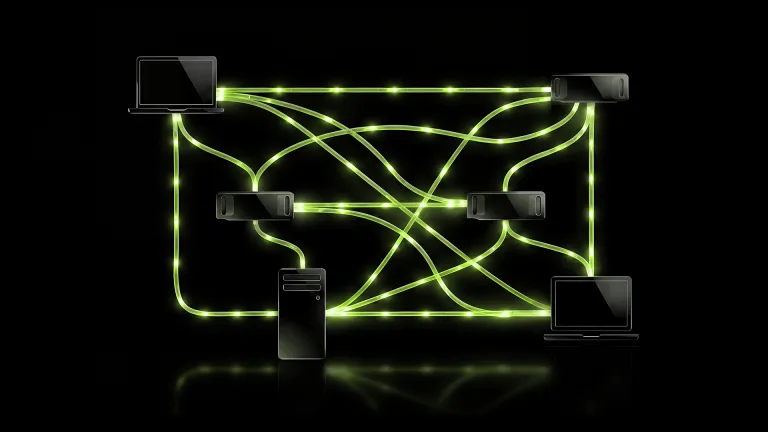
Complex AI systems requiring specialized models for coding, creative writing, and tool use quickly overwhelm individual workstations when a lead agent generates ten simultaneous sub-tasks. This computational demand inevitably triggers performance bottlenecks, including catastrophic slowdowns and out-of-memory errors that restrict workflow complexity before developers can fully realize their designs.
The fundamental challenge stems from VRAM volatility, which destabilizes performance when multiple large models compete for memory on a single device. The PAIR Virtual Inference Router resolves this by abstracting the entire local network into a unified compute resource pool. Unlike isolated machines, it operates as a dynamic load balancer specifically designed for LLM inference, intelligently distributing workloads across available GPUs and network nodes.
When ten sub-tasks emerge from a lead agent, the router analyzes cluster capacity to assign each task to the most suitable resource. This strategic distribution prevents any single device from becoming a choke point while ensuring specialized models run on hardware optimized for their specific memory and compute requirements. By eliminating manual model deployment and traffic management, PAIR allows developers to concentrate on workflow design rather than hardware constraints.
The system's scalability increases with each additional node, as the PAIR Virtual Inference Router automatically detects and integrates new resources into the compute pool. This dynamic expansion reduces latency while improving overall efficiency. By abstracting away hardware complexity, PAIR removes the physical limitations that previously confined sophisticated AI orchestration to basic chatbot capabilities, enabling seamless transitions toward complex, multi-model systems without workstation constraints.
All Replies (3)
Want a live back-and-forth? Join the global AI chat room — login to talk.
Agent clusters are a nightmare to manage. Do strict priority queues actually solve the resource drain for you? Running a swarm of AI agents is turning into a resource nightmare. Moving past simple chats toward complex multi-agent workflows shifts the computational burden. One large language model is no longer enough. A lead agent breaks down massive tasks into ten sub-tasks, each needing a specialized model for coding, creative writing, or tool use. Trying to run these sessions on one workstation hits a hardware wall instantly. VRAM consumption volatility is the main issue. Keeping several large models in memory at once causes catastrophic slowdowns or out-of-memory errors. This sets a limit on workflow complexity before hardware can no longer handle the orchestration. NVIDIA tackles this with their PAIR (Partner AI Research) Virtual Inference Router. Your local machine stops being an isolated compute island. Instead, your whole local network becomes a unified resource pool. It acts as a specialized load balancer for LLM inference. Implementing the PAIR Virtual Inference Router lets the system distribute workloads across multiple GPUs and network nodes. When a lead agent creates ten sub-tasks, the router checks cluster capacity and assigns each task to the best resource. This stops any single machine from bottling things up. Specialized models stay on hardware matching their specific memory and compute needs. This shift changes how developers and researchers use local AI. You stop trying to jam massive models into one GPU or sacrificing quality for VRAM budgets. PAIR enables a distributed approach. The route
I'm worried about sudden memory bottlenecks on single nodes. How does the load balancing actually handle that?
It helps to think of your local network as a unified resource pool rather than isolated islands. By using a Virtual Inference Router like NVIDIA’s PAIR, the system can distribute workloads across multiple GPUs and network nodes, assigning each sub-task to the best available resource so specialized models stay on hardware that matches their specific memory needs. This prevents any single machine from hitting a hardware wall when orchestrating complex multi-agent workflows.
My latency spikes are insane unless I pin the memory. Implementing the PAIR Virtual Inference Router lets the system distribute workloads across multiple GPUs and network nodes. Anyone else fighting this with PAIR?